
Picture a customer emailing at 9 p.m. to cancel an order. Your support AI replies within seconds: "Done. Your order is cancelled and your refund is on its way." Shopify agrees. The order shows as cancelled and refunded. But the order had already been passed to your third-party warehouse, and nothing told the warehouse to stop. Two days later, the parcel arrives, followed by an email asking why an order that was "cancelled" shipped anyway.
That scenario is hypothetical, but each step in it reflects documented product behavior. Gorgias, for example, states that cancelling an order in Shopify doesn't cancel it in the 3PL; if the order has already been submitted for fulfillment, you need a separate warehouse action (Gorgias). The AI understood the request and used a real action. The job still failed, at the last step, in a system the action didn't reach.
That gap between an answer and a finished job is the most useful way to choose an AI agent for ecommerce right now. Models are getting better at multi-step work, and the software you already pay for is absorbing more of it. Whether you gain anything depends on whether a tool can use the right business data, reach every system the job touches, and leave a result you can confirm.
Here is the short version:
- What an AI agent is. Software that takes a goal ("cancel this order if our policy allows it"), reads your store data, decides which steps to take and uses permitted tools to act, handing off to a person when it can't continue. Much of what's sold under the label is narrower: content generators, forecasting models, recommendation engines and fixed-rule automations. Those tools can be valuable, but they don't decide and act on their own.
- Which jobs are worth handing over. Repetitive work with a clear policy and a result you can check in a system of record: order-status questions, eligible cancellations, flow audits, recurring performance reports and draft purchase orders. Calls that depend on judgment, such as which product to launch, how much to reorder before peak season or whether to grant an exception, still need a person. AI can do the groundwork.
- Where to start. With the software you already pay for. Between September and late October 2026, Amazon, Klaviyo, Intercom, Triple Whale and Shopify all pushed new agent features into products merchants already use.
- When to add a tool or build one. Only when you can name the step your current tools can't complete—usually a write into another system, an approval rule or data they can't reach—and a new option demonstrably completes it.
- How to tell whether it worked. Don't count replies or drafts. Check the business record, such as the order, refund, warehouse status or published page, and count the jobs that ended in the right state. Then add the minutes people spent checking and fixing them.
Your first AI agent may already be in your admin
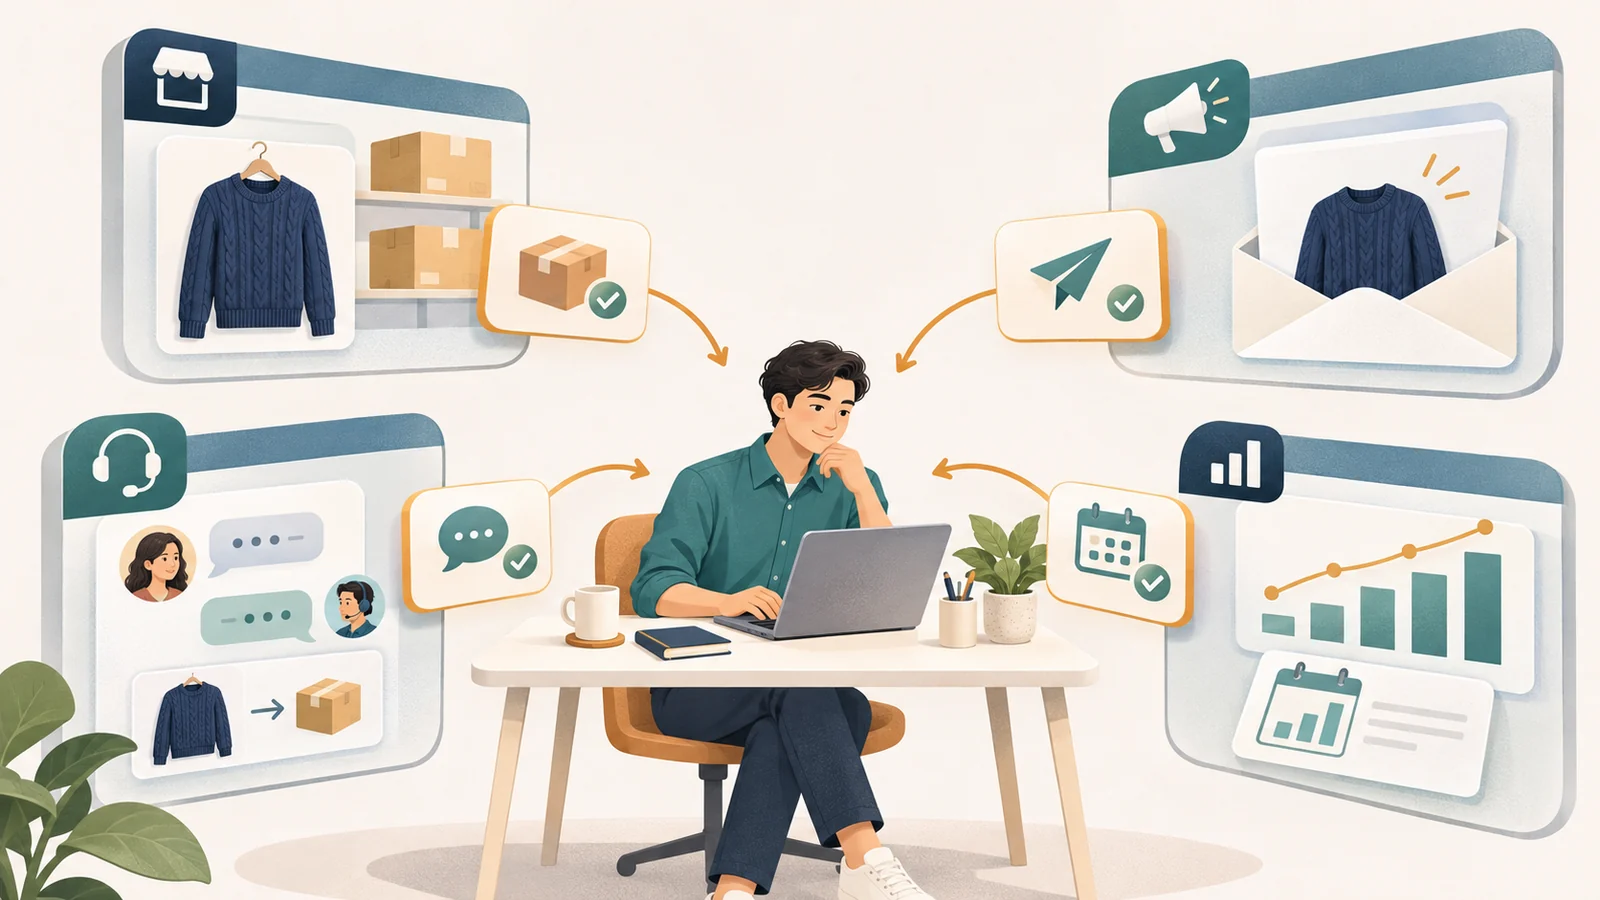
A year ago, "should we buy an AI agent?" usually meant evaluating a new vendor. The past three months changed that starting point, because the platforms that already hold your data started shipping agents themselves.
| Date (2026) | Product | What changed | Conditions to check |
|---|---|---|---|
| Sept. 9 | Klaviyo Composer | Scheduled tasks (such as a monthly performance summary), saved Skills for a team's own workflows and segment editing inside Composer. Klaviyo also opened 260+ MCP tools and 490+ APIs to outside AI assistants (Klaviyo) | SQL querying is a preview; Composer has a limited free allowance |
| Sept. 23 | Amazon Seller Assistant | Workflows that "continuously monitor and execute routine tasks like restocking and pricing adjustments," with audit trails and seller-defined guardrails, plus a plugin for Amazon Quick and, in beta, Claude (Amazon) | Confirm eligibility for your marketplace inside Seller Central |
| Oct. 7 | Intercom Fin 4 | Upgrades to the customer-facing agent, Operator Routines for back-office work, and Human in the Loop review (Intercom) | Check each sub-feature's status and plan; some are in beta |
| Oct. 8 | Triple Whale Moby | Moby in Slack for all customers, recurring reports, and Shopify landing pages built from product and ad data (Triple Whale) | Actions, automations and landing pages require Automate or Enterprise |
| Oct. 28 | Shopify Sidekick (Fall '26 Edition) | Sidekick can write and run code to forecast or compare store data, search the web, follow saved skills and build Shopify Flow workflows; connectors let merchants manage products, inventory and orders from external AI agents (Shopify, Shopify Help Center) | Canvas is in early access; not every capability is available to every store; the merchant approves changes |
These built-in agents start with an advantage that no new vendor can match on day one: they already have your data, your permissions and your billing relationship. Their limitation is the mirror image of that advantage. Each one works best inside its own platform. Connectors and MCP access extend their reach, but they don't by themselves put your warehouse, your helpdesk and your purchase orders under one agent's control. Klaviyo can't see your warehouse. Sidekick doesn't talk to customers. Moby can explain ad spend, but it can't supply product costs you never recorded.
So the buying question changes. It's no longer "which AI agent is best?" but "which part of this job does the agent I already have fail to finish?" If the answer is "nothing important," you've avoided a purchase. If the answer is specific, such as "it can't stop the order at our 3PL," you know exactly what a second tool must prove.
A note on model news: Anthropic says Claude Sonnet 5.5, released in late September, is stronger at long, multi-step work and cheaper per task than its predecessor (Anthropic). That's a good reason to retest a job you previously ruled out. It isn't evidence that your tools improved. Vendors choose their own models: Fin 4 shipped with Intercom's own Fin Apex 2.0 models, and when we checked on November 7, the "Auto" choice in AI by Zapier's Premium tier defaulted to Claude 4.6 Sonnet (Zapier). A model launch changes what's possible; only the product changes what you can use.
"Done" comes in five levels. Know which one you're buying
Vendors describe very different outcomes with the same words. "Handles cancellations" can mean that the tool drafts a reply, or that it changes the order, or that it changes the order and confirms that the warehouse stopped. Before you compare products, decide which of these levels a job needs:
| Level | What you get | Example | What your team still does |
|---|---|---|---|
| 1. Answer or report | Information, sometimes on a schedule | A Moby report posted to Slack every Monday; a Composer monthly summary | Decide and act |
| 2. Recommendation | A proposed action with its reasoning | Seller Assistant's inventory and pricing recommendations; restock alerts in an inventory planner | Approve or reject |
| 3. Draft | A prepared change that isn't live | A draft purchase order in Inventory Planner; a Flow that Sidekick built but you haven't turned on; Photoroom edits before you publish them to Shopify | Review and publish |
| 4. Executed action | A write in one system | Gorgias cancels an unfulfilled Shopify order; a Fin Procedure calls your refund API | Spot-check |
| 5. Verified outcome | The intended state, confirmed in every system the job touches | The order is cancelled in Shopify, the warehouse has confirmed a hold, and one refund for the right amount exists | Handle the exceptions |
Most tools on the market reach levels 1 to 3, and that can be exactly what you need. A weekly report that saves an analyst two hours is worth having. The trouble starts when a level 4 action is treated as a level 5 outcome, as in the cancellation story above, or when a level 1 report is described as "autonomous marketing."
Use the levels in two ways. First, choose the level the job requires: a sales summary needs level 1; a refund needs level 5. Second, check which level the tool actually reaches in your setup, with your warehouse, your plan and your permissions. The table below maps the eight workflows we cover on EcomAgentTools to the level that representative tools typically reach today.
| Workflow | Tools to start with | What they mainly do today | Typical level | When to add or build |
|---|---|---|---|---|
| Market research | Jungle Scout, SellerSprite | Amazon research databases with sales estimates, trackers and AI-assisted analysis | 1–2 | Rarely. The decision needs supplier quotes and a margin model |
| Product content | Canva Magic Studio, Photoroom | AI image, copy and batch editing tools | 3 | When volume outgrows manual review, not before |
| Store conversion | Rebuy; for enterprise catalogs, the Shopping Agent within Bloomreach Loomi | Rule-based and data-driven recommendations; conversational product guidance | 1–2, shown to shoppers | After your product data is accurate |
| Marketing | Klaviyo, BrazeAI | Analysis, audits and drafts; Braze's Decisioning Studio chooses messages within options you approve | 1–3, plus bounded execution | Seldom worth switching platforms for |
| Customer service and retention | Gorgias, Fin | Customer conversations, plus configured order actions | 4; 5 only when every affected system is connected | When the action must reach a system your helpdesk can't |
| Supply chain | Inventory Planner, Prediko | Forecasts, replenishment suggestions and purchase orders | 2–3 | When SKU count or lead-time complexity outgrows spreadsheets |
| Data and profit | Triple Whale, Polar Analytics | Unified reporting and natural-language analysis; Moby actions on higher tiers | 1 | When the problem is consistent definitions, not more questions |
| Automation and integration | Make AI Agents, n8n AI Agents, Zapier | Whatever you build | Set by your design | When a job crosses systems that no vendor connects |
Notice where level 4 and level 5 actually appear: customer service and whatever you build yourself. That's why the most instructive decisions sit there.
One cancellation, three right answers
Take a single job: a customer asks to cancel an order, and your policy allows it if nothing has shipped. The right tool depends less on which AI is smarter than on what your store is already running.
Store A runs Shopify, Gorgias and ShipBob. Gorgias's AI Agent has prebuilt Shopify Actions, including cancelling an unfulfilled order and restocking its items in Shopify; check how your configuration handles the refund. On its own, that action reaches level 4. Gorgias also documents separate Actions for 3PLs such as ShipBob and ShipStation, which lets the same conversation cancel the order at the warehouse. With both configured, this store can get close to level 5 without writing code, so adding a second agent would be hard to justify. One caveat: we found no documented step in Gorgias that pauses an individual cancellation for a person's sign-off in the way Fin's Procedures do. If your policy requires every refund to be approved, route those conversations to a person or build the approval step separately.
Store B runs Intercom and a warehouse with its own API. Here, Fin performs the action through a Procedure, the step-by-step instructions you write for a task, and through data connectors that call your systems (Intercom). That's more setup than Store A, because someone has to build and test the connector calls. In return, you can insert a "Loop in teammate" step that stops the Procedure until a person approves. If nobody responds in time, the conversation escalates to an owner you choose (Intercom).
The detail that decides whether this is safe lies in a second, similarly named feature. Fin's "Ask for input" escalation rule, currently in beta, lets a teammate review Fin's reply before it's sent. If you set a time limit and nobody answers, Fin sends its original draft (Intercom). That's reasonable for a reply about shipping times. It's the wrong control for a refund decision. Both features are called "human in the loop," yet they behave in opposite ways when nobody responds: one stops and escalates, while the other goes ahead and sends. When a vendor says "a human approves it," ask what happens when the human doesn't.
Store C handles 40 cancellations a month with two people. The honest answer may be to do nothing new. A person can cancel an order in Shopify admin in a minute or two, and Sidekick can prepare supported order changes for the merchant to confirm. Setting up, testing and monitoring an action agent costs hours that 40 cancellations won't repay quickly.
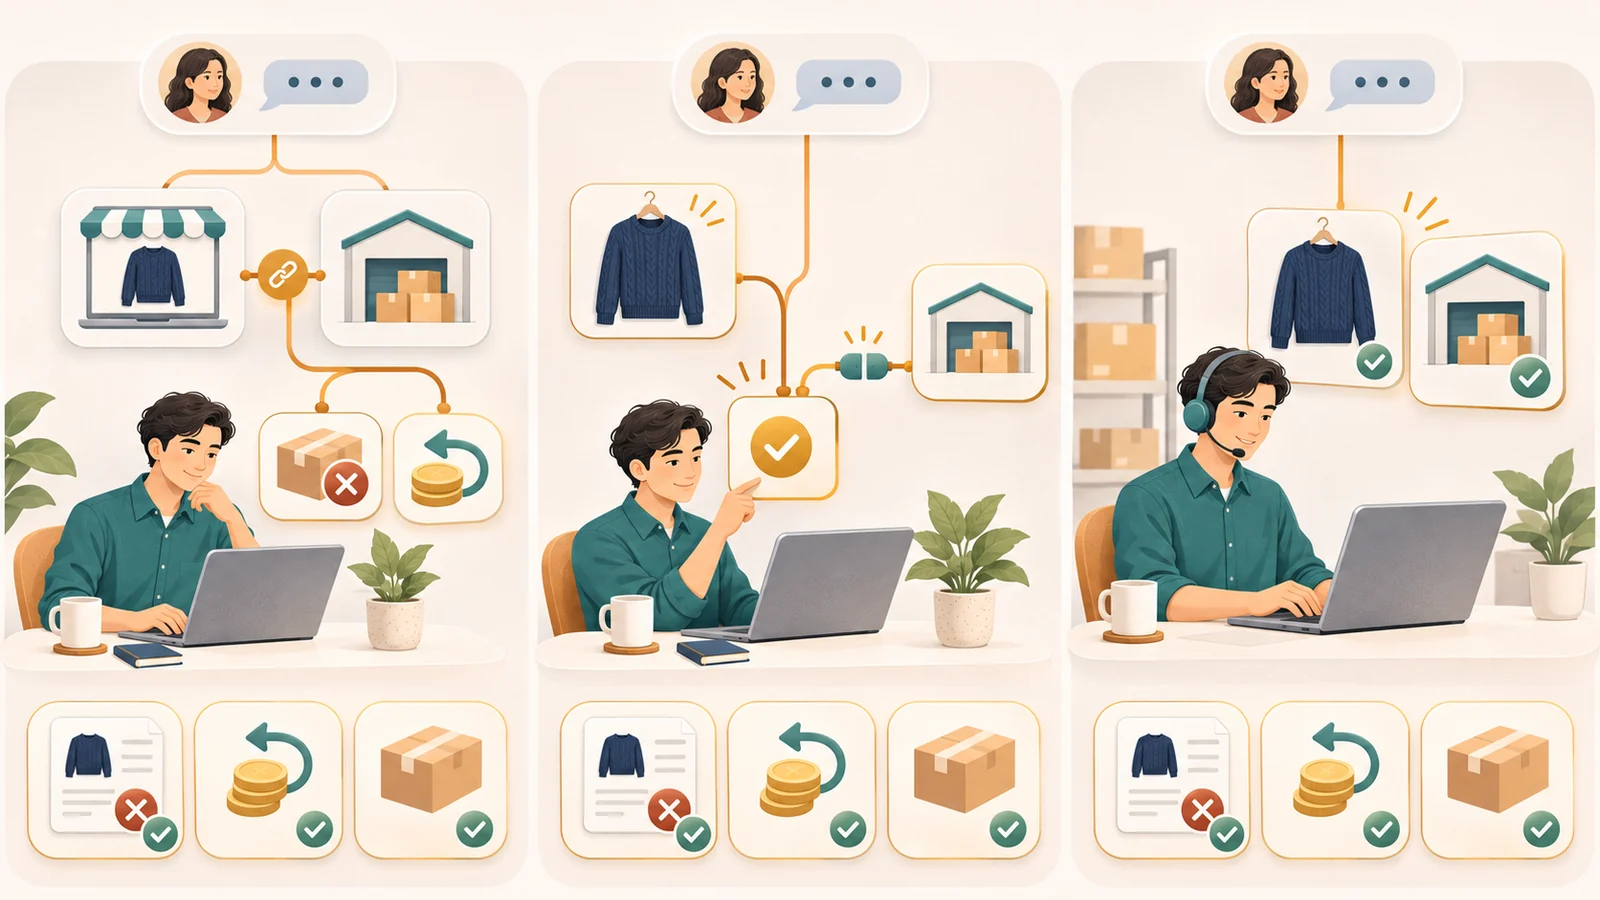
Whichever path fits, the evidence of success is the same: one cancelled order, one refund transaction for the right amount and currency, a warehouse confirmation, and a customer message that matches all three. Before going live, test the cases that break things: the same request arriving by email and chat, a partially fulfilled order, a warehouse that has already released the order for picking, and a refund call that times out so nobody knows whether it went through. That last case matters most. If the result is unknown, the agent should check whether a refund already exists before trying again, not simply retry.
Same workload, different bills
Customer service agents also show how pricing units can reverse a comparison. Intercom charges per seat plus a fee for each Fin outcome. Gorgias charges by ticket volume plus AI interactions, with no per-seat fee. To compare them fairly, you have to hold the work constant.
Here's a worked example using public monthly list prices in US dollars, checked on November 7, 2026. It's arithmetic, not a quote or a test result. Assume a Shopify store with two support staff and 300 conversations a month by email and chat. All of them are FAQs or read-only order-status questions, with no refunds or cancellations. AI fully resolves 200 conversations, and people handle 100. Assume both products produce exactly that result.
| Intercom Essential + Fin | Gorgias Basic with AI Agent | |
|---|---|---|
| Base | 2 full seats × $39 = $78 (Intercom seats) | $90 bundle: 300 helpdesk tickets and 30 AI interactions (Gorgias pricing) |
| AI usage | 200 outcomes × $0.99 = $198 (Intercom pricing) | 170 extra AI interactions × $1.50 = $255 |
| Tickets | Not billed per ticket | All 300 conversations count as tickets, including the AI-resolved ones, under Gorgias's current billing rules; they fit within the 300 included (Gorgias billing) |
| Monthly software subtotal | $276 | $345 |
On those assumptions, Intercom is $69 cheaper. Change one input and the order flips:
- Add staff. With four full Intercom seats, the Intercom side rises to $354 ($156 + $198), while the Gorgias figure stays at $345, because Gorgias doesn't charge per seat.
- Automate less. If AI resolves 50 conversations instead of 200, the Intercom side drops to $127.50 ($78 + $49.50), while the Gorgias side drops to $120 ($90 + 20 × $1.50), and Gorgias becomes the cheaper option.
Several limits apply. The $345 is a public-bundle calculation, not Gorgias's lowest possible price: Gorgias lets you raise your AI allowance in advance to avoid overage charges, and we didn't obtain a price for prepaying 200 interactions. Intercom's pricing page defaults to annual billing and advertises a 35% discount for new customers, so its headline seat price is lower than the $39 monthly rate used here. Fin counts an outcome when it resolves a conversation or completes a Procedure up to a configured handoff; Intercom says you aren't charged if the customer asks for a person, and a reopened conversation is refunded. Most importantly, this read-only scenario tells you nothing about whether either base plan includes the Procedures, approvals and 3PL actions that the cancellation job needs. Price the job you actually want automated, then add the costs that never appear on a pricing page: setup time, review time, and fixing what goes wrong.
Marketing: when the agent you already have is enough
Marketing is where the "start with what you own" rule pays off most clearly, because the newest capabilities landed inside platforms that merchants already use.
Take a recurring chore: checking a live Klaviyo flow for expired discount codes, broken links and products that are out of stock. In Klaviyo, Composer can audit a flow and suggest fixes, and since September, it can run scheduled tasks and reuse a team's saved Skills. Every Klaviyo customer gets a free Composer plan with 500 credits per cycle. A $20 monthly plan includes 2,000 credits, and optional flexible overages buy another 1,000 credits for $10, charged in full even if you use only part of the increment. Klaviyo estimates that auditing one flow, form or template uses between $0.10 and $4.50 of capacity, depending on its size and complexity (Klaviyo Help Center). At the paid plan's rate, the free allowance is worth $5, so a few large audits can use it up.
For a Klaviyo store, that's a cheap, low-risk trial. Copy one flow, run the audit and record what it finds. Then keep two numbers separate: problems found and problems fixed. A finding is level 1. A fix counts only after someone applies it and the live flow shows the change. If Composer flags an expired code and a marketer has to correct it, you've saved review time, not the whole job.
Klaviyo's MCP access means you could run the same audit from a general assistant such as Claude or ChatGPT. That's useful if your team already works there, but it adds a permissions question. A connected assistant that can write to Klaviyo needs the same review rules as Composer.
BrazeAI serves larger teams already on Braze, and it shows why "AI" in a product name says little about the level it reaches. BrazeAI Operator helps staff build content, segments and Canvas journeys from plain-language requests, which is production help at the draft level. Decisioning Studio does something different. Within the subject lines, offers and frequency your team approves, it chooses what each customer receives and when. That's genuine autonomous execution, but only within the boundaries you set. Neither tool is a reason to migrate an email platform. If Klaviyo or Braze already runs your messaging, test the agent inside it before you evaluate a separate marketing agent.
One stock number, five jobs
The flow audit lives inside one system. The cancellation story showed what happens when a job crosses two. Many expensive mistakes involve jobs that cross five. Consider another hypothetical: your best-selling navy sweater in size M drops to four units, and the next delivery is two weeks away. That single fact needs to reach at least five places:
- Replenishment. Inventory Planner turns forecasts into suggested quantities and purchase orders that move from draft to approved to open (Inventory Planner). Its Shopify connector imports new orders and current stock levels in a daily sync, not in real time, so check when the data was last updated before trusting "days of stock left" (Inventory Planner). Prediko offers a Shopify-native buying table with restock alerts and purchase-order creation. In both cases, creating a purchase order is not the same as a supplier accepting it.
- Marketing. The Klaviyo flow from the previous section may still feature the sweater in a browse-abandonment or promotional email.
- Onsite discovery. Recommendations from Rebuy, or a conversational shopping assistant, may keep suggesting the variant. If shoppers' needs can be expressed as filters such as color, size, price and in-stock status, Shopify's free Search & Discovery filters may solve the problem without any conversational agent. Intercom's own setup guide for Fin for Ecommerce warns that with pre-order, made-to-order or restricted-stock products, Fin may match the wrong product page and give customers inaccurate availability information; it recommends a Guidance rule for those cases (Intercom).
- Support. Agents, human or AI, need the same delivery date. If nobody has confirmed one, they should say so rather than guess.
- AI shopping channels. Shopify Catalog sends your products' titles, descriptions, options, images, prices and availability to AI channels and keeps inventory and prices updated. If key data lives in custom fields, you need to map it before those channels can read it correctly (Shopify Help Center).
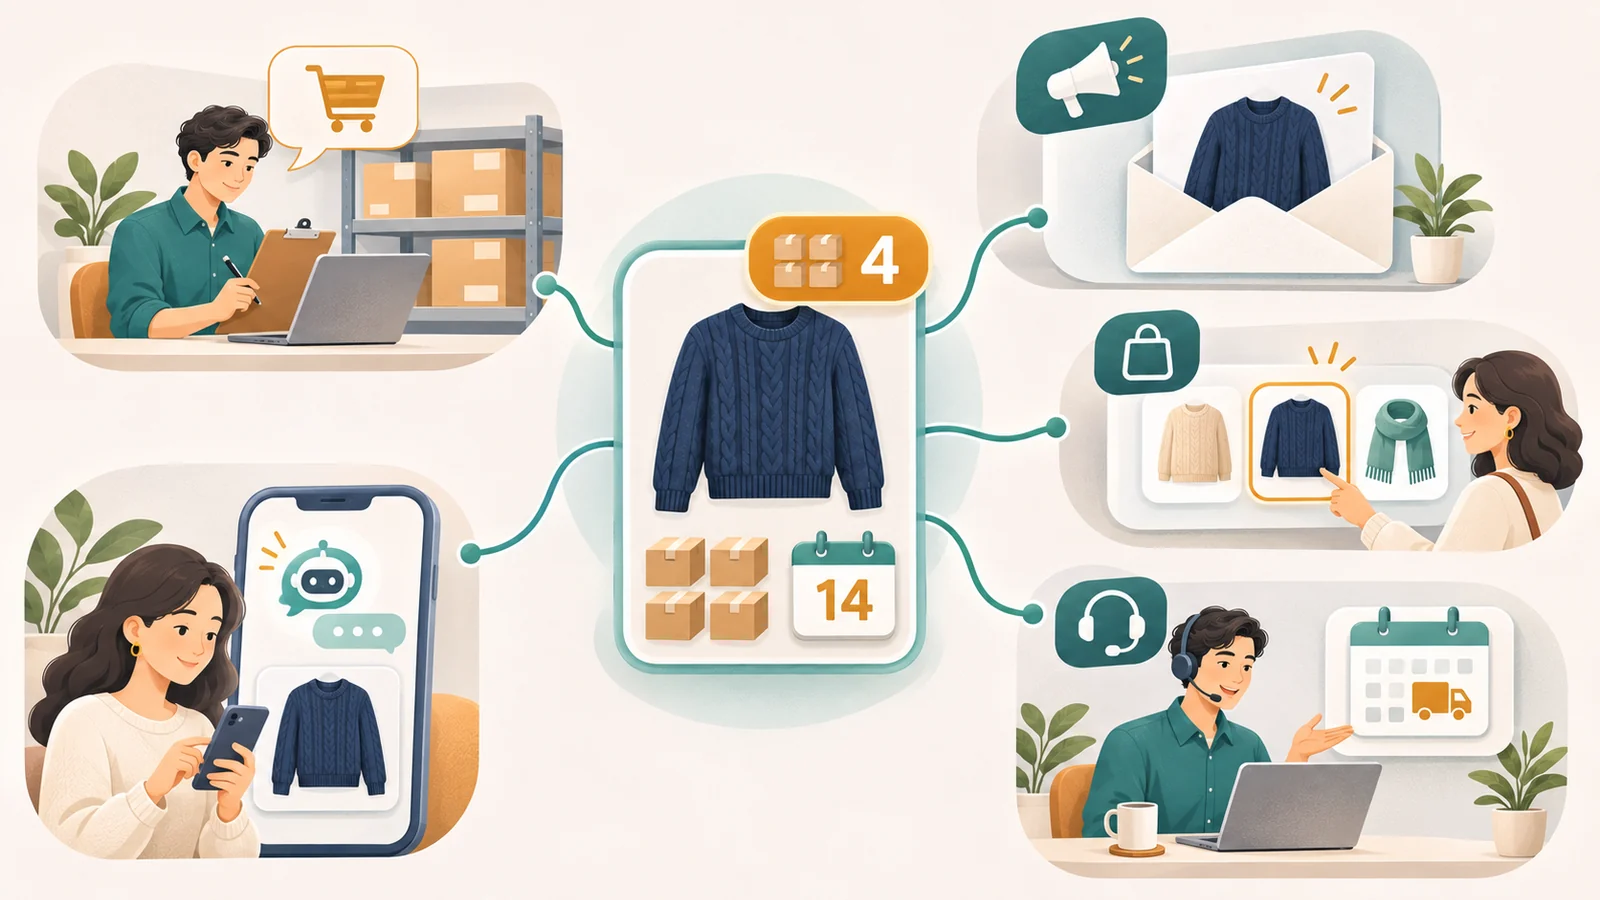
Each of those tools has its own rules or agent. None of them owns the shared fact. That's why adding agents can make things worse: every new one is another place where a stale stock count can turn into a wrong promise. What helps is unglamorous. Use one SKU or variant ID everywhere, agree on which system holds the true stock number, keep timestamps on every copy, and name an owner for each action, such as pausing the email, changing the delivery message or approving the purchase order.
The same logic applies to product content. Photoroom and Canva Magic Studio make scenes, variants and resized images cheap to produce. Neither is an autonomous agent. They're content tools that stop at level 3. Photoroom's Shopify workflow changes store images only when someone publishes the edited images back to the store (Photoroom), and that review step is where the real work moves. When images cost almost nothing, the risk shifts to accuracy: whether the color matches the actual fabric, whether the right image sits on each variant, and whether a generated scene implies a size or feature the product doesn't have. AI shopping channels will read and repeat whatever your catalog says, so accurate product data now affects sales beyond your own store.
Build the connecting work only where judgment is needed
When a job crosses systems that no vendor connects, you build. The useful rule is to use the simplest tool for each step.
- Fixed rules first. "If available stock for a variant falls below five, tag it and notify the buyer" needs no AI. Shopify Flow is a free Shopify app that does this reliably, and it's easy to audit.
- An AI step only for judgment. Classifying a messy customer email or deciding which of three teams owns an exception does benefit from a model. In AI by Zapier, each run uses tasks according to the model tier and the number of successful tool calls. A run with two tool calls costs 9 tasks on the Advanced tier and 15 on Premium, which is the default for new steps. Three hundred such runs a month add up to 2,700 or 4,500 tasks before you count the other steps in the Zap (Zapier). Tools run without pausing unless you turn on "Require approval before running" for each one.
- Migrations change behavior. Zapier is moving Zapier Agents into AI by Zapier. It hasn't set a shutdown date, but its guide asks you to turn off the original agent after publishing the converted Zap, so the same action doesn't run twice. Some knowledge sources aren't supported yet (Zapier). Our Zapier Agents page covers the older product.
- More control, more responsibility. Make AI Agents puts agents inside visual scenarios billed in credits. n8n can be self-hosted, which gives you control over data and runtime but also makes you responsible for credentials, monitoring, backups and upgrades.
In any of them, let the model propose and let a fixed step check the order ID, amount, currency and whether the action already ran before anything is written. That division of labor is a design choice you make. None of these platforms guarantees it by default.
Amazon sellers start from a different place
Everything above assumes a Shopify or DTC store where you choose the helpdesk, the email platform and the connectors. On Amazon, Seller Central is the system of record, and its agent sits inside it.
For research, Jungle Scout and SellerSprite are research tools with AI features, not agents. Jungle Scout's sales estimates and opportunity scores are directional inputs, and its AI Assist allowance varies by plan. SellerSprite records competitor prices, rankings and new listings in daily snapshots, so it doesn't capture every change in between, and its API and MCP access are sold separately from the website subscription. Both help narrow a list of niches to the few worth investigating, which is level 1 or 2. The decision to order inventory still needs supplier quotes, landed cost and a margin model. Don't let a sales estimate turn into a purchase order without that step.
For operations, Seller Assistant's new workflows are the closest thing to a level 4 agent most Amazon sellers can use. Amazon says they can monitor and execute routine tasks such as restocking and pricing adjustments within guardrails you set (Amazon). Treat the guardrails as the real work. A price floor should be your margin floor after fees and advertising, not a round number. Then review the audit trail regularly, at least at first. Check which marketplaces your account can use before you plan around the feature.
Two cautions apply to sellers on both channels. Shopify tools such as Sidekick, Flow and Rebuy don't operate on Amazon listings, so a multichannel seller needs inventory data that both sides share, and the connector should be verified rather than assumed. And "supports 100 languages" is not the same as selling well in another market. Customer messages may translate perfectly, while the tool still lacks access to that marketplace, its currency, its tax rules or your warehouse there.
How to tell whether a trial finished the job
A trial should answer one question: does the tool finish this job reliably, and at what total cost compared with the way you do it now? You need four things to answer it.
A written end state. Describe it in system terms: "Order cancelled in Shopify, hold confirmed by the 3PL, one refund in the original currency." Avoid outcomes such as "customer satisfied."
The same inputs for every option. Run your current process and each candidate against the same normal cases and the same awkward ones: duplicate requests, stale data, missing lead times, insufficient permissions and partial failures. Our trial record template lists 28 such test designs, each with a starting state, an expected result and the evidence to check. They're designs, not results. The actual-result columns are blank for you to fill in.
A record per run. Note the level reached, the read-back evidence, the minutes spent reviewing and repairing, and the usage units consumed.
The right unit of success. Divide total cost, including software, review time and repair time, by the number of verified completed jobs. Twenty replies drafted and five orders correctly cancelled are not the same result. Then check the business numbers the job was meant to move, such as repeat contacts, refund errors, returns, response time or margin. A tool that costs more per job can still be the right choice if it answers faster, converts more or makes fewer mistakes; the point is to measure those gains rather than assume them.
Those business numbers have their own trap. Before you ask an agent why margin fell last week, check whether the data can answer. Shopify's profit reports only cover products with a cost recorded at the time of sale (Shopify Help Center). An agent will still produce a plausible explanation for a margin figure, including one that is wrong because half your SKUs have no cost. Triple Whale's Moby can schedule reports and, on higher tiers, take actions. Its "Ask every time" setting queues each action for your approval, while "Let Moby decide" may run supported actions in live accounts without asking (Triple Whale). Polar Analytics builds a managed warehouse and a shared set of metric definitions that dashboards, audience tools and its Headless MCP all use. Pay for that kind of foundation when inconsistent definitions are the problem. Don't buy it because an analytics agent sounds clever. If costs are missing, fix the cost data first. No model can work around missing costs.
What 2027 is likely to change, and what would change this advice
The following are judgments based on what has already shipped, not predictions with dates attached.
Platform agents will cover more routine work. Shopify, Amazon, Klaviyo and Intercom have each moved from answering questions toward scheduled and executed work within a single quarter. If that continues, standalone tools will increasingly need to prove a step the platform can't finish. This view should change if, by mid-2027, the native features still mostly produce reports and drafts while people carry the same workload.
Approval will be designed per action. The Fin example shows that "human in the loop" can mean opposite behavior when someone doesn't respond. Expect buyers to ask, action by action, who approves, how long the system waits and what happens next.
Bills will follow work done, so cheaper models won't automatically mean lower bills. Outcomes, credits and tasks already scale with usage. A vendor can use a model that costs less per task and still run more steps, retries or premium tiers. Track the cost per verified job over time instead of assuming it will fall.
Your product data will work harder outside your store. As AI shopping channels read catalogs directly, accurate variants, availability and policies will affect whether a product is recommended correctly. Discovery is one thing; checkout is another. Shopify documents checkout through AI channels as handing off to the merchant's checkout, or completing it directly where eligible (Shopify). Check each step separately for your store and region.
Operators will spend less time on steps and more on exceptions. When drafts and reports arrive on their own, the valuable work becomes setting the goal, checking the result and handling the cases the system can't. That shift has already started in the tools above. How far it goes depends on whether the shared facts underneath, stock, orders and costs, become reliable enough to trust.
Your next move
List the three jobs your team repeats most often. For each one, write down the level of "done" it needs and the level your current tools reach in your setup. Wherever those two levels differ, you've found the specific gap that a new tool or a small build must close. Everywhere else, use what you already have, and measure it by finished jobs.
Comments
Share experience or ask a question. Comments are plain text; any external link is automatically marked nofollow.
No comments yet.